The End of FutharkScript
This post is about replacing FutharkScript, a bespoke and very limited language for talking to compiled Futhark programs, with actual Futhark. The main challenges are the interaction between interpreted and compiled Futhark code, and how to shoehorn IO into Futhark.
Background
Futhark is not a general-purpose language. Instead, a Futhark program is
compiled to a library, which can then be invoked from other
languages. Since it would
be very awkward to write programs in other languages whenever you want to
test, benchmark, or demonstrate Futhark code, we have some tools that can
directly talk to compiled Futhark code. One of these is futhark literate,
which is intended for writing documents that mix prose and the evaluation of
Futhark code. For example, we can define a simple function:
def linspace (n: i64) (start: f64) (end: f64) : [n]f64 =
  tabulate n (\i -> start + f64.i64 i * ((end - start) / f64.i64 n))
And then use “directives” to show the result of evaluating the code on some input:
> linspace 5 1 20[1.0f64, 4.8f64, 8.6f64, 12.399999999999999f64, 16.2f64]In fact, this very blog post is a Literate Futhark program that has been
automatically converted to Markdown by futhark literate, with the result of
evaluation spliced in where appropriate.
Other directives allow us to interpret the results of Futhark code as images:
def linspace_2d n start end : [n][n](f64, f64) =
  map (\x -> map (\y -> (x, y)) (linspace n start end))
      (linspace n start end)

def spirals n v : [n][n]f64 =
  let f (x, y) = f64.sgn (f64.cos (f64.sqrt (x ** 2 + y ** 2)))
  in map (map f) (linspace_2d n (-v) v)
> :img spirals 200 30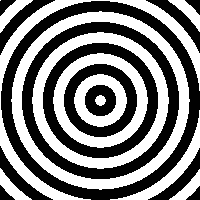
This is a lovely feature that I use often. However, it does have some quirks.
The largest quirk is that the code that you put in the directives (like
spirals 200 30) is not actually real Futhark code, but a different
language called FutharkScript, which looks so
much like Futhark that it causes occasional confusion. It is an extremely
austere language, without such features as arithmetic, or really any way of
manipulating values. All FutharkScript can be used for is calling (compiled)
Futhark entry point functions, and passing the results on to other entry
points or return them from directives. FutharkScript is even dynamically
typed, very much unlike Futhark itself.
On the upside, FutharkScript also has some features not found in Futhark
itself, such as a magical $loaddata function that accepts a file name,
interprets the file contents using Futhark’s binary data
format,
and returns the resulting values. This of course makes no sense in Futhark
itself, but it is convenient for writing demonstrations or tests that operate
on data stored in files - certainly more so than writing a small C or Python
program that does the IO on Futhark’s behalf.
That said, being limited to FutharkScript sucks. It is very annoying that the
evaluation directives used in futhark literate cannot show the evaluation
of arbitrary Futhark code. The workaround is to put them in a normal
definition, which we can then reference from FutharkScript, but this can get
awkward, and the whole point of futhark literate is to produce documents
that are nice to read.
It would be much nicer if directives could contain normal Futhark code.
However, this runs into a constraint that I don’t want futhark literate to
generate code - as far as the Futhark compiler is concerned, the directives
are written as comments, and the program is compiled without reference to
them. This is in order to ensure that the view that futhark literate has of
a program is the same as that a normal program would have. This means that
directives have to be interpreted. That is not a problem at first glance,
since Futhark of course has an
interpreter, but because our
interpreter is so slow, we still want the ability to invoke compiled Futhark
programs. Basically, this is the architecture of futhark literate:
Compile the Futhark program in exactly the same way we would compile any Futhark program intended to be invoked by other programs, in particular not paying attention to directives.
futhark literateloads the entire program into the interpreter, again not caring about directives.futhark literatenow evaluates directives, dispatching any mentions of entry points to the compiled Futhark program.
Note that step 3 could also be “read and interpret Futhark expressions provided interactively by the user” - so this can also help make Futhark’s REPL more effective.
To replace FutharkScript with real Futhark, we need to figure out how to replace the only features FutharkScript possesses:
How can the Futhark interpreter invoke compiled code?
How do we allow interpreted Futhark code to perform IO?
How the Futhark interpreter invokes compiled code
This problem was worked on by Marcus Jensen, an MSc student here at
DIKU. The basic idea is not so difficult: the Futhark
interpreter has access to a compiled Futhark program, and it can invoke its
entry points. Since we assume that we also have access to the source code, we
essentially just intercept some function calls, namely the ones corresponding
to entry points in the compiled program, and handle them differently. For
example, suppose a Futhark program defines functions foo and bar where
the latter is defined as an entry point, then compiling that program will
produce a compiled version of bar. If we then in the context of the program
execute foo (bar x), then bar will be run with compiled code, and the
result passed on to foo, which will be interpreted. Our main interest is of
course the case where the interpreted part comes from directives, or perhaps
even directly from the user, in a REPL-like situation.
The main challenge is how to translate between the interpreter value representation and the compiled code value representation. We had to make a bunch of extensions to the C API and Futhark server protocol, because it turned out that we did not provide enough facilities for decomposing truly arbitrary Futhark values into their constituent parts, but now we do. (Except for an edge case related to arrays of sum types.) I consider it a testament to the strength of value-oriented programming that this kind of translation, although tedious, is ultimately not hard.
Another challenge, which is more thorny than really difficult, is bridging the essential manual memory management of Futhark’s external interface with the garbage-collection-based memory management of Futhark’s interpreter, which is written in Haskell. As previously covered on this channel, Futhark’s interpreter is explicitly written to be straightforward, so we did not want to rewrite it to use manual memory management through reference counting. Ultimately the solution is careful use of Haskell’s finalizers in a way that is clever, but ultimately just an implementation detail. For those curious about these details, I expect that Marcus will hand in his thesis one of these days. (The main challenge is that when a finalizer runs, the compiled Futhark program may not be in a state where it allows us to free objects, so instead we push it onto a work-queue for later.)
How we allow interpreted Futhark code to perform IO
The most unusual feature of FutharkScript compared to Futhark is the
availability of functions for reading files. Now, Futhark really is pure
with no escape, but the reason we cannot
compromise on that is because it would make the aggressive optimisation we do
in the Futhark compiler much more difficult to perform. Since the interpreter
is specifically intended to evaluate the program in a “natural” way, it is
actually possible to shoehorn in magical impure functions. In a way we
already support that, as the trace function prints a message to the
terminal. In FutharkScript, the impure functions are denoted by a leading
$, but in order to not modify the syntax, I decided to expose this
functionality to interpreted Futhark as a prelude module called io, which
provides these functions, where [k]u8 should be be seen as a file name:
module io
: {
    -- | Return the contents of the given file as a byte array.
    val loadbytes [k] : [k]u8 -> ?[n].*[n]u8


    -- | Reads an image from the given file and returns it as a row-major
    -- array, with each pixel encoded as ARGB.
    val loadimg [k] : [k]u8 -> ?[n][m].*[n][m]u32


    -- | Read audio from the given file and returns it as a ``[][]f64``, where
    -- each row corresponds to a channel of the original soundfile.
    val loadaudio [k] : [k]u8 -> ?[n][m].*[n][m]f64


    -- | Load a Futhark value of known type (including size!) from the given
    -- file. If the type is a tuple, the file must contain one value for
    -- each element.
    val loadvalue 'a [k] : [k]u8 -> *a
  }
These correspond to what was available in FutharkScript, with one important
change. In FutharkScript we have access to $loaddata, which returns the
contents of a Futhark data file. Since the type of the result depends on the
file contents, this does not fit Futhark’s static type discipline. Therefore,
the replacement io.loadvalue function requires the type including the
size to be known in advance. This is awkward in practice: if we want to read
an array of integers from a file, we must know exactly how big the array is
expected to be in advance. For example: io.loadvalue "array.data" : [100]i32. The root limitation is that Futhark’s size
types do not allow a type parameter to
be instantiated with an “existentially unknown size”. If we simply did
io.loadvalue "array.data" : []i32, the type checker would complain about
the size being ambiguous, except of course if something else constrains the
return size in some way.
We did use $loaddata in various places for writing benchmarks, and so I had
to change for example this input directive for a benchmark:
{ (256i64, $loaddata "data/randomSeq_100M_256.in") }to instead read like so:
{ (256i64, io.loadvalue "data/randomSeq_100M_256.in" : [100000000]i32) }Is this the end of the world? Not really - it is just a bit more of a hassle. We will have to see whether it is intolerable.
The functions in the io module are of course only usable in interpreted
code, and if you attempt to use them in compiled Futhark code, the compiler
will refuse to compile your program. There is actually a detail here that I
am somewhat dissatisfied with, because the error is not detected by the type
checker (which has no idea whether the code is “compiled” or “interpreted”),
but far later in the compilation pipeline, which is contrary to our policy of
compiling anything that passes the type checker. We may clean that up in the
future, although I do not have much appetite for adding much complexity just
to handle this edge case in an ideologically more pure way.
What happens next
The above is implemented as part of this pull
request, which remains
unmerged as of this writing. I intend to ruminate a bit more on the changes,
but I will likely merge them soon. Apart from making futhark literate a bit
more flexible, these changes also allow futhark repl to interpret
expressions in the context of a compiled program, running all entry points at
full compiled speed, while allowing the user to enter and run arbitrary
interpreted Futhark code.